
Products / 01 Extract
Collect product data. Skip the scraper upkeep.
Managed ecommerce scraping: give us a public product or catalog URL and its market. We build and validate the crawler, then collect structured product data when you need it.
Product pagetempo.example
Homme › Chaussures › Baskets
NIKE Air Max 90 Black
134,99 €
Taille 42
En stock
Livraison offerte dès 50 €
↳ 1 Capture · /products/airmax90-black-42 · 1 Sep 09:00
The output
From a product page to a record you can use.
A real Capture from a Nike product page. Switch to the JSON to see what your application receives.
Men > Basketball > Shorts
Men's Dri-FIT Basketball Shorts
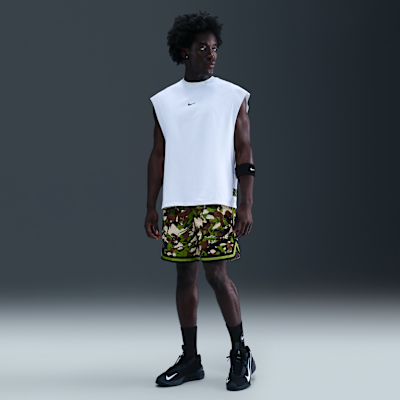 1 / 6
Description
Built for the court, ready for anywhere. These lightweight-yet-durable basketball shorts help keep you cool with our sweat-wicking Dri-FIT technology.
Details
- Recycled Materials
- Designed for Basketball
- Unlined
- Lightweight, sweat-wicking fabric with mesh and smooth interior
- Side pockets and zippered utility pocket large enough for a phone
- Elastic waistband with drawcord
- Body: 100% polyester. Pocket bags: 100% polyester.
- Machine wash
- Imported
- Shown: Chlorophyll/Black
- Style: HV1878-350
Specifications
- Style
- HV1878-350
- Shown
- Chlorophyll/Black
Attributes
- Color
- Chlorophyll/Black
- Gender
- MEN
- Age group
- Adult
- SKUs
- 7
Tags
1 Capture. What the page said, its URL and when it was seen, in the same fields as every other store.
Product details
Titles, descriptions, brand, categories, media and the properties the page exposes.
Variants and identifiers
Options, configurations, SKUs and product identifiers, when the page has them.
Offers and availability
Prices, currencies, sellers, condition and availability, as seen in the market you chose.
URL and observation time
The page each Capture came from and when it was extracted, so every record can be checked.
Under the hood
Written by AI. Run as code.
AI studies each store once, writes its crawler and proves it on real pages before your first run. Every page after that runs through compiled code, not a model, so extraction never invents a value. Here is the crawler for an example store in France.
# reverse-engineer the API
- detectplatformcustom storefront✓
- recordproduct pageloaded twice · 41 requests✓
- selectproduct APIGET /api/v2/products/{id} · JSON✓
- replayover HTTP200 · same fields✓
# write the crawler
- mapcatalogsitemap + 18 categories · 12,480 products✓
- generateextractorRust · 26 fields✓
- compilereleasenative library · no model per page✓
# prove it
- validate3 live pages26/26 fields on each✓
- checkprovenanceevery value found on its page✓
- readycrawler v1
# run · 1 Sep 09:00 UTC
- routeFR residentialexit country FR✓
- fetch12,480 productsvia the store API, over HTTP
- retry37 challengesnew fingerprint and IP✓
- done12,316 Captures164 pages failed, no credits✓
# redesign · 3 Nov
- score3 Nov run14% accepted · below 20%✕
- stoprun pausedrejected pages not written
- rebuildcrawler v2new product template · 3/3 pages✓
- resume3 Nov run12,402 Captures✓
detect · record · select · replay
Reverse-engineers the store’s API.
We load a product page, record every request it makes and find the internal API that returns the product: the same one the store’s own frontend calls. Replayed over plain HTTP, it gives the full product in clean JSON, and changes less often than a page layout. Shopify, WooCommerce and Wix have native routes; embedded JSON comes next, HTML last.
# reverse-engineer the API
- detectplatformcustom storefront✓
- recordproduct pageloaded twice · 41 requests✓
- selectproduct APIGET /api/v2/products/{id} · JSON✓
- replayover HTTP200 · same fields✓
map · generate · compile
Writes a crawler for this website.
A model maps the catalog and writes the extraction code once, in Rust. It compiles to a native library, so every page after that runs as plain code: no model call per page, and the same page always gives the same record.
# write the crawler
- mapcatalogsitemap + 18 categories · 12,480 products✓
- generateextractorRust · 26 fields✓
- compilereleasenative library · no model per page✓
validate · check
Proves it on real pages.
Before your first run, the crawler has to extract every required field from 3 live product pages. Each value must come from the page itself: a crawler that invents or hard-codes a value does not ship.
# prove it
- validate3 live pages26/26 fields on each✓
- checkprovenanceevery value found on its page✓
- readycrawler v1
route · fetch · retry
Collects from inside the market.
Residential IPs in the store’s country, with the exit country checked. Each page comes from the store’s reverse-engineered API, or over plain HTTP where there is none. Cloudflare, DataDome, Akamai and other anti-bot challenges are detected and retried with a new fingerprint and IP.
# run · 1 Sep 09:00 UTC
- routeFR residentialexit country FR✓
- fetch12,480 productsvia the store API, over HTTP
- retry37 challengesnew fingerprint and IP✓
- done12,316 Captures164 pages failed, no credits✓
score · rebuild · resume
Heals when the site changes.
Every run scores what it extracts. When a redesign breaks the crawler, the run stops before bad records reach your data, and AI rebuilds it, proves it again and puts it back to work.
# redesign · 3 Nov
- score3 Nov run14% accepted · below 20%✕
- stoprun pausedrejected pages not written
- rebuildcrawler v2new product template · 3/3 pages✓
- resume3 Nov run12,402 Captures✓
From setup to maintenance
Skip the scraping project.
Getting those records normally means building and operating a scraping stack. We do that work: we generate and validate the crawler, then run and repair it whenever you need fresh data.
With a scraping stack, you
- Design the extraction schema
- Write extraction scripts
- Handle dynamic pages
- Manage crawlers
- Run browsers and sessions
- Configure proxies
- Handle retries and failures
- Monitor extraction quality
- Repair site changes
With Extralt, you give
- 01a URL
- 02a few minutes
Pricing
1 credit per product page. However hard the site.
Extract uses a credit each time it turns a product page into a Capture. Sitemaps, catalog pages, failed or blocked pages, residential IPs, retries, and crawler builds and repairs use none. Credits cost from $1 per 1,000 on Scale; Enrich adds 1 more per page.
FAQ
Questions about Extract.
Start with your stores
Start with the ecommerce pages you need.
Add a public product or catalog URL and its market. Collect structured records you can inspect, enrich, compare and reuse.
Start for free · No credit card · Plans from $30/month